 SupplierX
 OrderX
 Xpense
 LogystiX
 ManufeX
 AeonXIQ
The Observability Gap in ML Systems: How We Built a Model Health Dashboard That Catches Degradation Before Users Do
The Silent Failure Problem: Why Your ML Model Can Break Without Throwing a Single Error
Application monitoring is a solved problem. When a microservice goes down, CloudWatch fires an alarm. When a database query exceeds its timeout, an alert reaches the on-call engineer within seconds. The system fails loudly, and the team responds.
Machine learning models fail quietly.
There is no exception stack trace when a demand forecasting model starts systematically underestimating peak demand because the business launched a new product category that doesn't exist in the training data. There is no 5xx error when a churn prediction model's accuracy drops from 84% to 61% because the customer acquisition team changed the onboarding flow three months ago and the behavioral signals the model depends on have fundamentally shifted. There is no CloudWatch alarm — by default — when the feature distribution your model was trained on has drifted far enough from today's production data that the model's predictions are no longer reliable.
The system keeps running. The API keeps returning predictions. The business keeps making decisions on those predictions. And the degradation compounds silently until someone notices that the outcomes don't match expectations anymore — by which point weeks or months of quietly wrong predictions have already influenced inventory decisions, customer communications, or resource allocations.
When we encountered this problem on a production ML platform at an enterprise retail client — a demand forecasting model that had been live for eight months and had gradually drifted to the point where its predictions were less accurate than a simple moving average — the business impact was measurable: overstocked inventory on slow-moving SKUs, stockouts on fast movers, and a planning team that had quietly stopped trusting the model but hadn't escalated it formally.
The model hadn't broken. It had drifted. And the infrastructure had no way to see it happening.
This post documents the model health monitoring architecture we built to solve that problem — using Amazon SageMaker Model Monitor, custom Amazon CloudWatch metrics, Amazon QuickSight dashboards, and Amazon Bedrock-powered anomaly narration — so that model degradation is caught in days, not months.
As Technical Architect for this initiative at AeonX Digital, I designed the monitoring architecture, defined the drift thresholds, and worked with the data science team to establish what "healthy" looks like for each model in production. What follows covers the implementation decisions, the specific metrics that matter, and the lessons that only emerge when you've watched a model degrade in production and traced it back to its root cause.
The outcome: mean time to detect model degradation reduced from an average of 47 days to under 72 hours, three separate drift incidents caught and corrected before business impact materialized, and a planning team that trusts the model again — because they can see its health in real time.
Why This Matters Now: The ML Observability Blind Spot in Enterprise AI
Three patterns are converging to make model observability an urgent priority for every enterprise running ML in production:
- The production ML footprint is growing faster than the monitoring capability — Teams that started with one model in production now have eight. Each model was deployed with ad-hoc monitoring — a scheduled accuracy check here, a manual data quality review there. That approach doesn't scale. When something goes wrong with model number six, nobody is watching it closely enough to notice.
- Data environments are less stable than they appear — Business events that seem unrelated to ML — a pricing change, a new market segment, a shift in customer acquisition channel, a supplier change — frequently alter the statistical properties of the data the model relies on. Input distributions shift. Feature correlations change. The model was trained on a world that no longer exists, and it has no way to signal that.
- Regulatory and audit requirements are catching up to AI adoption — Enterprises in BFSI, healthcare, and retail are beginning to face questions from auditors and regulators about how they know their AI models are performing as intended. "We check the accuracy quarterly" is no longer a satisfactory answer. Continuous monitoring with documented thresholds and response procedures is becoming the expected standard.
The decision to build this monitoring platform was driven by a business leadership team that had experienced one silent failure and was not willing to experience another without knowing about it first.
The Business Problem
The enterprise retail client's ML platform had:
- Four models in production: demand forecasting, churn prediction, price elasticity estimation, and supplier lead time prediction
- No automated drift detection — model performance was reviewed manually in quarterly business reviews
- No feature distribution monitoring — nobody was tracking whether the data flowing into production models matched training data distributions
- No alerting pipeline — model issues were surfaced by downstream business complaints, not proactive monitoring
- No model version history linked to performance metrics — when a retrained model underperformed, there was no fast path back to the previous version
Business impact of the status quo:
- The demand forecasting model drifted for approximately 11 weeks before the planning team raised a formal concern — by which point inventory positioning decisions for two peak-demand periods had been influenced by unreliable predictions
- No structured way to answer the question: "Is this model still working as well as it was when we deployed it?"
- Data science team spending significant time on reactive investigation rather than model improvement
- Business stakeholders losing confidence in AI-driven recommendations without a clear explanation of why
The goal was not to build better models — the models were reasonable. The goal was to build the visibility infrastructure that ensures model quality in production is continuously validated, not periodically hoped for.
Technical Architecture
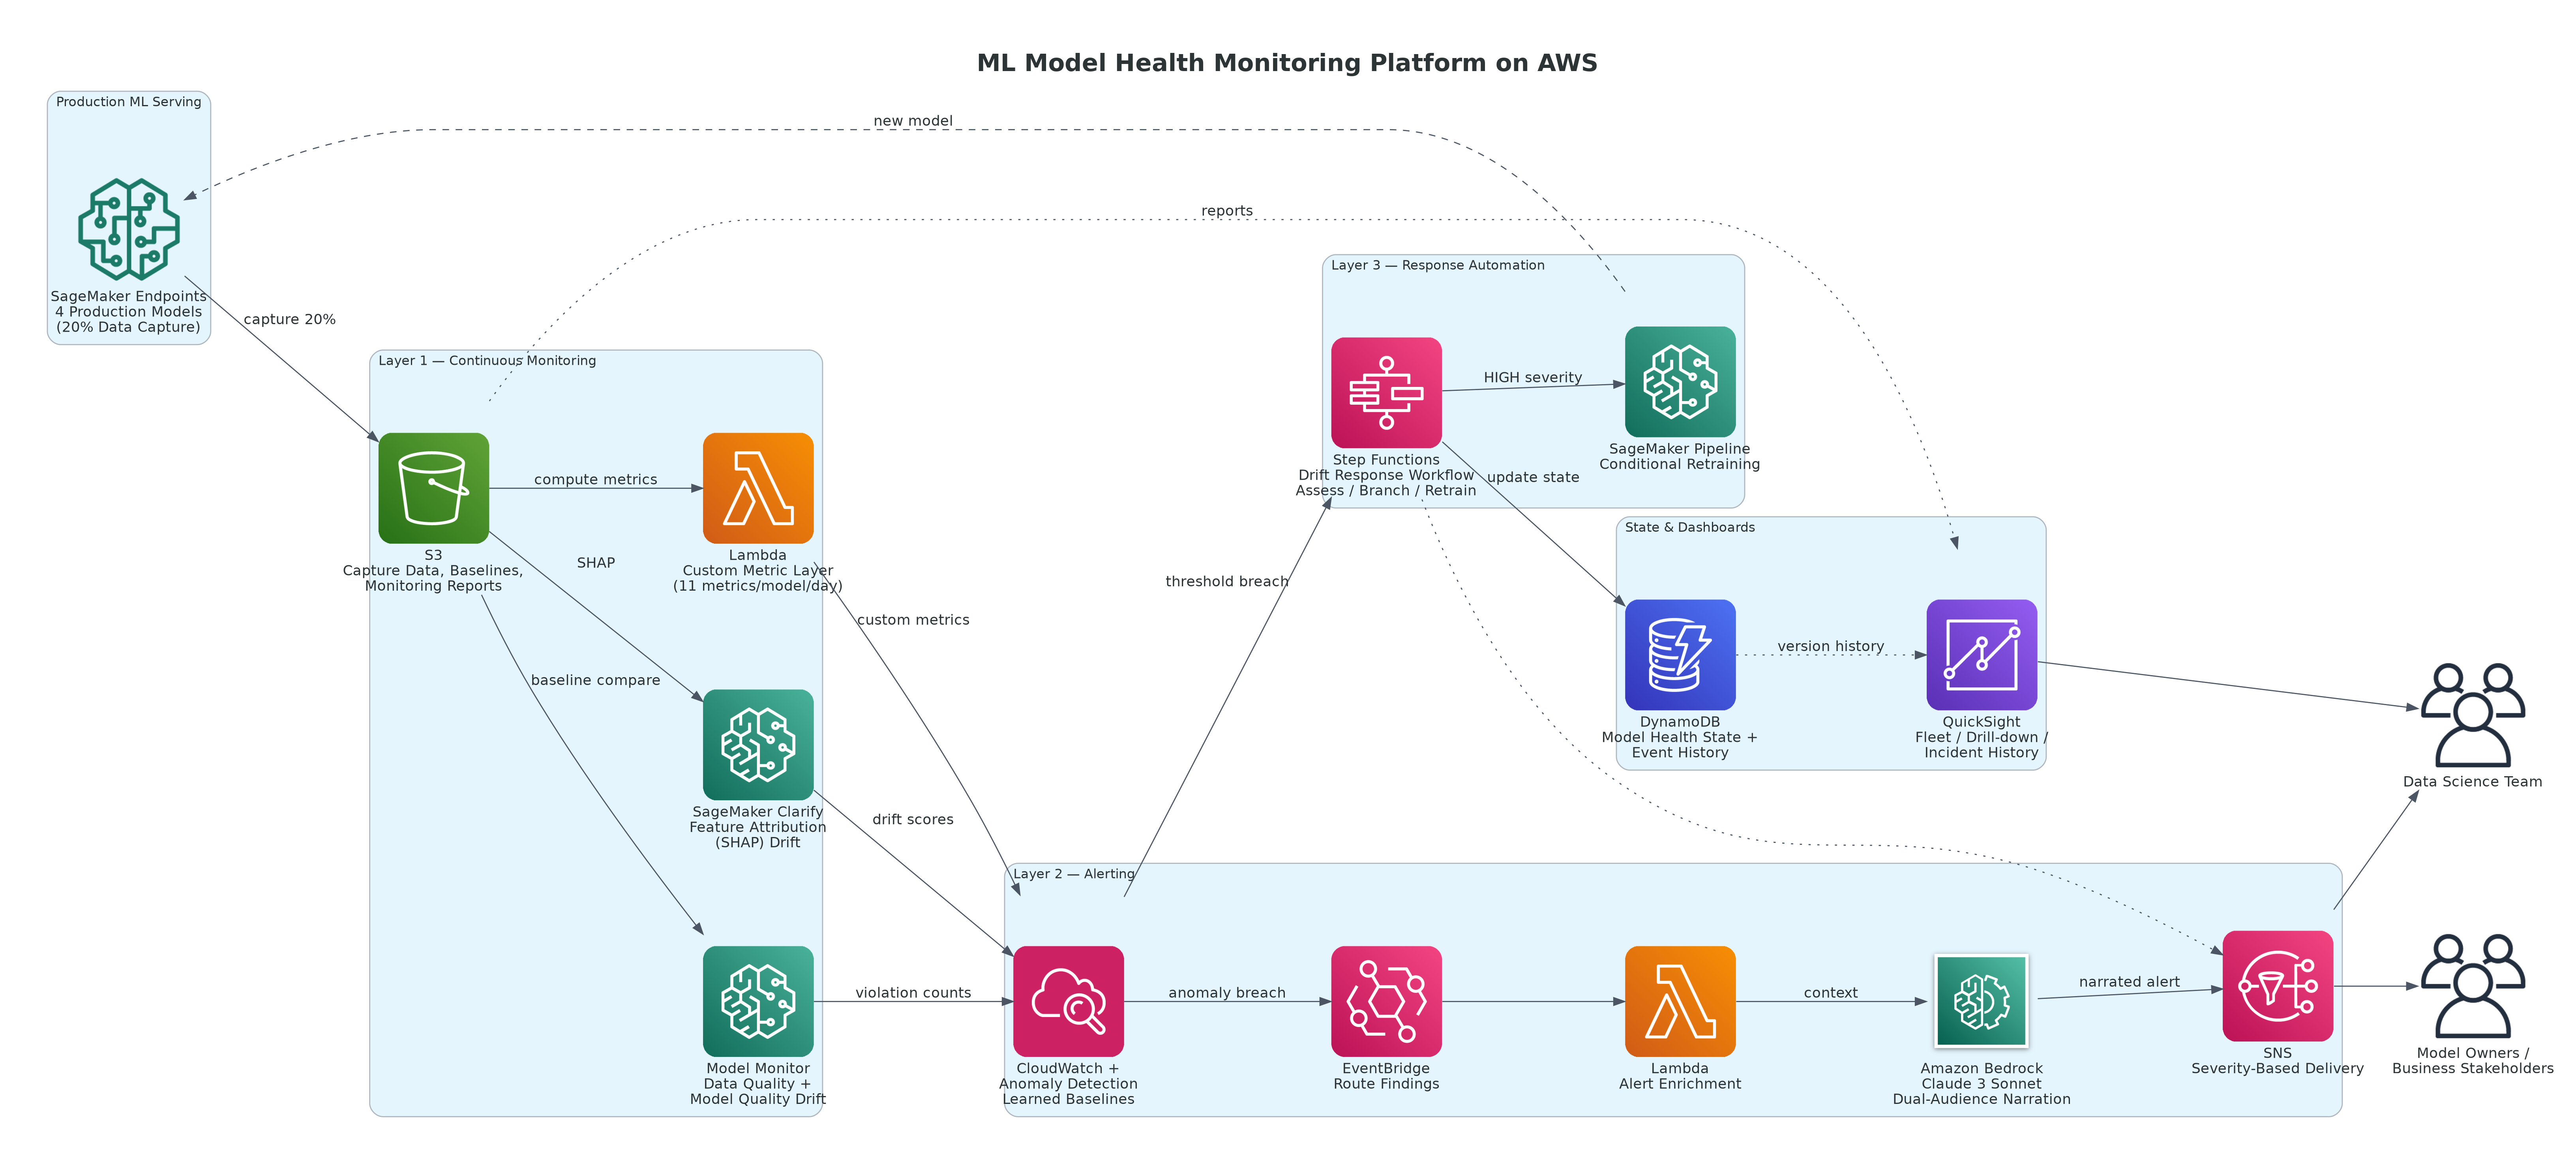
Figure 1: ML Model Health Monitoring Platform — Three-Layer Observability Architecture on AWS
AWS Services Used:
- Amazon SageMaker Model Monitor — automated data quality, model quality, feature attribution drift, and bias drift monitoring
- Amazon S3 — baseline statistics storage, monitoring reports, and model artifacts
- Amazon CloudWatch — custom metrics for prediction distribution, confidence score trends, and business-outcome correlation
- Amazon CloudWatch Anomaly Detection — ML-powered baseline for metric anomaly alerting
- Amazon EventBridge — routing Model Monitor findings to downstream alerting and response workflows
- AWS Lambda — custom metric computation, alert enrichment, and automated response triggers
- Amazon SNS — alert delivery to data science team, model owners, and business stakeholders
- Amazon QuickSight — model health dashboards with drill-down from fleet-level to individual feature level
- Amazon Bedrock (Claude 3 Sonnet) — natural language narration of drift findings for non-technical stakeholders
- Amazon DynamoDB — monitoring event history and model health state store
- AWS Step Functions — automated investigation and retraining trigger workflow
The architecture is organized into three layers: continuous monitoring that runs automatically against every production endpoint, alerting that routes findings to the right people at the right severity level, and response automation that initiates retraining when drift crosses defined thresholds.
Key Architectural Decisions
These are the decisions that shaped the monitoring platform — and the reasoning behind each one.
Decision 1: Why SageMaker Model Monitor Instead of Custom Monitoring Scripts?
When we began designing this platform, the data science team already had a collection of ad-hoc monitoring scripts — Python jobs that ran on a schedule, computed accuracy metrics against a sample of recent predictions, and emailed a CSV to a distribution list. The proposal to replace them with SageMaker Model Monitor initially met resistance: "We already have monitoring."
The gap was in what those scripts didn't catch. Custom accuracy scripts require ground truth labels — which for demand forecasting means waiting 30–90 days for actual sales data to come in before you can measure prediction accuracy. By the time the accuracy script fires an alert, the model has been making poor predictions for weeks.
SageMaker Model Monitor's data quality monitoring works on the input features themselves — no ground truth required. It detects when the distribution of inputs to the model has shifted away from the training baseline, which is an early warning signal for impending accuracy degradation, often days or weeks before accuracy metrics show it.
| Monitoring Type | What It Catches | Ground Truth Required | Detection Lead Time |
|---|---|---|---|
| Custom accuracy scripts | Accuracy drop after the fact | Yes — often 30–90 day lag | Days to weeks after degradation |
| SageMaker Data Quality Monitor | Input feature distribution shift | No | Days before accuracy impact |
| SageMaker Model Quality Monitor | Prediction accuracy vs. ground truth | Yes | When labels arrive |
| SageMaker Feature Attribution Drift | SHAP value shifts across features | No | Days before accuracy impact |
| Custom CloudWatch metrics | Business outcome correlation | Partial | Configurable |
The business decision: Data quality and feature attribution monitoring give you early warning before accuracy degrades. Accuracy monitoring tells you the model has already failed. For a business that makes decisions daily on model outputs, early warning is worth more than post-hoc confirmation.
Decision 2: Why Build a Custom Metric Layer on Top of Model Monitor?
SageMaker Model Monitor produces statistical monitoring reports — violations, constraint comparisons, distribution summaries. What it does not produce natively is business-aligned metrics: prediction confidence trend over the past 14 days, percentage of predictions in the high-confidence band vs. the uncertain band, correlation between model confidence and actual outcome accuracy, or the rolling 7-day prediction error by product category.
These are the metrics that business stakeholders can understand and act on. They are also the metrics that catch failure modes that statistical drift monitoring misses — specifically, cases where input distributions appear stable but the model's confidence is systematically shifting, which often precedes an accuracy drop on a specific segment of the data.
We built a Lambda-based custom metric layer that runs alongside Model Monitor, computing and publishing 11 custom CloudWatch metrics per model per day. CloudWatch Anomaly Detection then establishes a learned baseline for each metric and alerts when the metric deviates beyond the expected band.
The business decision: Statistical drift metrics are for data scientists. Business-outcome metrics are for the model owners who decide whether to retrain, adjust thresholds, or escalate. Both layers are necessary. Neither is sufficient alone.
Decision 3: Why Amazon Bedrock for Alert Narration?
A SageMaker Model Monitor violation report looks like this:
feature_name: units_sold_30d
constraint_check_type: distribution_statistics
description: Completeness check failed. Expected 0.98, Got 0.71
That output is actionable for a data scientist. It is not actionable for the demand planning manager who owns the model's business outcomes and needs to decide whether to hold a manual forecast review while the issue is investigated.
We added an Amazon Bedrock narration layer that converts Model Monitor violation reports and CloudWatch anomaly findings into plain-language summaries targeted at two audiences: a technical summary for the data science team and an executive summary for the model owner.
Example narration generated for a data quality violation on the demand forecasting model:
For the data science team: The units_sold_30d feature is showing 27% missing values in today's scoring batch, compared to a 2% baseline at training time. This is likely caused by a data pipeline upstream of the feature store — the feature relies on transaction data from the ERP integration, and the completeness drop coincides with the ERP maintenance window scheduled last night. Check the Glue ETL job for sales_transactions_daily before triggering retraining.
For the demand planning team: The demand forecasting model has detected an issue with one of its input data sources from last night. Today's predictions may be less reliable than usual for SKUs in the Electronics and Appliances categories. We recommend treating today's forecast output as indicative rather than definitive until the data science team confirms the issue is resolved — estimated by end of day.
That second paragraph is what prevents a business stakeholder from either ignoring a real issue or escalating a routine data pipeline hiccup into an emergency. It sets the right level of concern, in language that matches the audience, without requiring the data science team to write it manually for every alert.
The business decision: Monitoring without communication is incomplete. The alert needs to reach the right person with the right context and the right recommended action. Bedrock makes that possible at scale without manual effort.
Implementation Pattern
Setting Up SageMaker Model Monitor
Model Monitor requires three components per endpoint: a baseline computed from training data, a monitoring schedule that runs against live traffic, and a violation handler that routes findings downstream.
import boto3
import sagemaker
from sagemaker.model_monitor import (
    DefaultModelMonitor,
    DataCaptureConfig,
    CronExpressionGenerator
)
from sagemaker.model_monitor.dataset_format import DatasetFormat

sagemaker_session = sagemaker.Session()
role = sagemaker.get_execution_role()
bucket = "ml-monitoring-bucket"
endpoint_name = "demand-forecast-endpoint-prod"

# Step 1: Enable data capture on the endpoint
# This captures a sample of inference requests and responses to S3
data_capture_config = DataCaptureConfig(
    enable_capture=True,
    sampling_percentage=20,          # Capture 20% of traffic — sufficient for drift detection
    destination_s3_uri=f"s3://{bucket}/data-capture/{endpoint_name}",
    capture_options=["Input", "Output"],
    csv_content_types=["text/csv"],
    json_content_types=["application/json"]
)

# Apply to endpoint — update in place, no redeployment required
predictor = sagemaker.predictor.Predictor(
    endpoint_name=endpoint_name,
    sagemaker_session=sagemaker_session
)
predictor.update_data_capture_config(data_capture_config=data_capture_config)

# Step 2: Compute baseline statistics from training data
monitor = DefaultModelMonitor(
    role=role,
    instance_count=1,
    instance_type="ml.m5.xlarge",
    volume_size_in_gb=20,
    max_runtime_in_seconds=3600,
    sagemaker_session=sagemaker_session
)

monitor.suggest_baseline(
    baseline_dataset=f"s3://{bucket}/training-data/baseline.csv",
    dataset_format=DatasetFormat.csv(header=True),
    output_s3_uri=f"s3://{bucket}/baseline-results/{endpoint_name}",
    wait=True
)

# Step 3: Create daily monitoring schedule
monitor.create_monitoring_schedule(
    monitor_schedule_name=f"{endpoint_name}-data-quality-monitor",
    endpoint_input=endpoint_name,
    output_s3_uri=f"s3://{bucket}/monitoring-reports/{endpoint_name}",
    statistics=monitor.baseline_statistics(),
    constraints=monitor.suggested_constraints(),
    schedule_cron_expression=CronExpressionGenerator.daily(),
    enable_cloudwatch_metrics=True      # Publish violation counts to CloudWatch
)
Feature attribution drift monitoring runs in parallel using SageMaker Clarify, tracking SHAP value distributions across features to detect when the model's reliance on specific features has shifted — a subtler but often more informative signal than raw data distribution drift.
from sagemaker.clarify import (
    SageMakerClarifyProcessor,
    ModelConfig,
    ModelPredictedLabelConfig,
    SHAPConfig,
    DataConfig
)

clarify_processor = SageMakerClarifyProcessor(
    role=role,
    instance_count=1,
    instance_type="ml.m5.xlarge",
    sagemaker_session=sagemaker_session
)

shap_config = SHAPConfig(
    baseline=[
        # Baseline values for each feature — use training set means
        [2847, 0.73, 14.2, 3, 1, 0.91, 28, 0, 1, 0.84]
    ],
    num_samples=500,
    agg_method="mean_abs",
    save_local_shap_values=False
)

clarify_processor.run_explainability(
    data_config=DataConfig(
        s3_data_input_path=f"s3://{bucket}/data-capture/{endpoint_name}/recent/",
        s3_output_path=f"s3://{bucket}/explainability/{endpoint_name}",
        label="prediction",
        dataset_type="text/csv"
    ),
    model_config=ModelConfig(
        model_name="demand-forecast-model-v4",
        instance_type="ml.m5.xlarge",
        instance_count=1
    ),
    explainability_config=shap_config
)
Custom CloudWatch Metric Layer
The Lambda function runs daily after Model Monitor completes, pulling the captured inference data from S3, computing business-aligned metrics, and publishing them to CloudWatch under a custom namespace.
import boto3
import json
import numpy as np
from datetime import datetime, timedelta

s3 = boto3.client("s3")
cloudwatch = boto3.client("cloudwatch", region_name="ap-south-1")

def compute_and_publish_model_metrics(endpoint_name: str, bucket: str):
    """
    Compute business-aligned health metrics from captured inference data
    and publish to CloudWatch for anomaly detection and dashboarding.
    """
    # Load last 24 hours of captured inference data from S3
    prefix = f"data-capture/{endpoint_name}/{datetime.utcnow().strftime('%Y/%m/%d')}/"
    response = s3.list_objects_v2(Bucket=bucket, Prefix=prefix)

    predictions = []
    confidence_scores = []

    for obj in response.get("Contents", []):
        data = json.loads(
            s3.get_object(Bucket=bucket, Key=obj["Key"])["Body"].read()
        )
        for record in data.get("captureData", {}).get("endpointOutput", {}).get("data", []):
            pred = float(record.get("prediction", 0))
            conf = float(record.get("confidence", 0))
            predictions.append(pred)
            confidence_scores.append(conf)

    if not predictions:
        return

    metrics = [
        # % of predictions in high-confidence band (>0.80)
        {
            "MetricName": "HighConfidencePredictionRate",
            "Value": sum(1 for c in confidence_scores if c > 0.80) / len(confidence_scores),
            "Unit": "None"
        },
        # Mean confidence score — a downward trend precedes accuracy drops
        {
            "MetricName": "MeanPredictionConfidence",
            "Value": float(np.mean(confidence_scores)),
            "Unit": "None"
        },
        # Coefficient of variation — unusually high variance signals instability
        {
            "MetricName": "PredictionCoefficientOfVariation",
            "Value": float(np.std(predictions) / np.mean(predictions))
                     if np.mean(predictions) != 0 else 0,
            "Unit": "None"
        },
        # Predictions outside historical interquartile range — outlier rate
        {
            "MetricName": "OutOfRangePredictionRate",
            "Value": sum(
                1 for p in predictions
                if p < np.percentile(predictions, 5) or p > np.percentile(predictions, 95)
            ) / len(predictions),
            "Unit": "None"
        }
    ]

    cloudwatch.put_metric_data(
        Namespace=f"MLModelHealth/{endpoint_name}",
        MetricData=[
            {**m, "Timestamp": datetime.utcnow(), "Dimensions": [
                {"Name": "EndpointName", "Value": endpoint_name},
                {"Name": "Environment", "Value": "production"}
            ]}
            for m in metrics
        ]
    )
CloudWatch Anomaly Detection is then configured on each custom metric to establish a learned band based on 14 days of history. When a metric breaches the anomaly band, EventBridge routes the finding to the alert enrichment Lambda, which queries the monitoring history, assembles context, and calls Bedrock for narration before dispatching to SNS.
Bedrock Alert Narration
import boto3
import json

bedrock = boto3.client("bedrock-runtime", region_name="ap-south-1")

def narrate_drift_alert(alert_context: dict) -> dict:
    """
    Convert raw monitoring findings into plain-language summaries
    for two audiences: data science team and business model owner.
    """
    prompt = f"""You are an ML observability analyst. A production model health alert has been triggered.

Alert Details:
- Model: {alert_context['model_name']}
- Endpoint: {alert_context['endpoint_name']}
- Alert type: {alert_context['alert_type']}
- Triggered metric: {alert_context['metric_name']}
- Current value: {alert_context['current_value']}
- Expected range: {alert_context['expected_range']}
- Violation summary from SageMaker Model Monitor: {alert_context['violations']}
- Recent business context: {alert_context['business_context']}
- Model purpose: {alert_context['model_purpose']}

Write two summaries:

1. TECHNICAL SUMMARY (for the data science team): Explain what metric triggered, what it likely means technically, what to investigate first, and whether retraining is likely needed. Be specific.

2. BUSINESS SUMMARY (for the model owner): Explain in plain language what is happening, how it might affect decisions made using this model today, and what action they should take (if any) while the team investigates. Avoid technical jargon. Maximum 3 sentences.

Respond as a JSON object with keys: technical_summary (string), business_summary (string), recommended_action (string: one of INVESTIGATE, RETRAIN, ESCALATE, MONITOR)."""

    response = bedrock.invoke_model(
        modelId="anthropic.claude-3-sonnet-20240229-v1:0",
        contentType="application/json",
        accept="application/json",
        body=json.dumps({
            "anthropic_version": "bedrock-2023-05-31",
            "max_tokens": 600,
            "temperature": 0.1,     # Very low temperature — consistent, factual narration
            "messages": [{"role": "user", "content": prompt}]
        })
    )

    result = json.loads(response["body"].read())
    return json.loads(result["content"][0]["text"])
Automated Response: Step Functions Retraining Workflow
When drift severity crosses a defined threshold — specifically, when data quality violations exceed 15% of monitored features or feature attribution drift exceeds 0.25 on any top-5 SHAP feature — Step Functions triggers an automated investigation and conditional retraining workflow.
CloudWatch Alarm (drift threshold breached)
    → EventBridge rule
    → Step Functions: ModelDriftResponseWorkflow
        → State 1: AssessViolationSeverity
              Query Model Monitor reports from last 3 days
              Compute trend: is drift accelerating or stable?
        → State 2 (branch on severity):
              LOW: Publish enhanced monitoring alert, increase
                   capture sampling to 50%, notify data science team
              MEDIUM: Trigger data validation job on feature store,
                      notify model owner + data science team,
                      schedule retraining review in 48 hours
              HIGH: Trigger SageMaker Pipeline retraining immediately,
                    notify all stakeholders, flag predictions
                    as "under review" in the serving layer
        → State 3: UpdateModelHealthState (DynamoDB)
        → State 4: NotifyStakeholders (SNS → Bedrock narration)
This workflow means that a high-severity drift event triggers an automatic retraining run without requiring a data scientist to manually initiate it at 2am — while still routing appropriate notifications so the team can validate the retrained model before it goes live.
QuickSight Model Health Dashboard
The QuickSight dashboard consumes data from three sources: Model Monitor reports stored in S3, custom CloudWatch metrics exported via a Lambda-based ETL to S3, and model version history stored in DynamoDB. It is organized in three views:
- Fleet view: All four production models at a glance, with a RAG (Red/Amber/Green) health status for each based on composite drift score. The first screen any data science team member sees in the morning.
- Model drill-down: Per-model view showing data quality violation trend (30 days), feature attribution drift per feature (heatmap), confidence score trend, and prediction distribution vs. training baseline.
- Incident history: Timeline of all drift alerts, the Bedrock-generated narratives, actions taken, and time-to-resolution — building the audit trail that compliance and leadership need.
Cost Architecture and AWS Service Spend
At steady-state monitoring four production SageMaker endpoints with daily monitoring schedules:
| Service | Usage | Estimated Monthly Cost |
|---|---|---|
| SageMaker Model Monitor | 4 endpoints × daily schedule, ml.m5.xlarge processing | ~$96 |
| SageMaker Clarify (SHAP drift) | 4 runs/week × ml.m5.xlarge | ~$58 |
| Amazon S3 | ~180 GB (capture data, reports, baselines) | ~$4 |
| Amazon CloudWatch | 44 custom metrics, anomaly detection on 16 metrics, 120 alarms | ~$38 |
| AWS Lambda | ~180K invocations/month (metric computation + alert enrichment) | ~$2 |
| Amazon Bedrock (Claude 3 Sonnet) | ~60 narration calls/month (alert events only) | ~$1 |
| AWS Step Functions | ~12 workflow executions/month | ~$1 |
| Amazon SNS | ~200 alert notifications/month | ~$1 |
| Amazon QuickSight | 3 authors, 8 readers | ~$54 |
| Amazon DynamoDB | Monitoring state store, low volume | ~$3 |
| Total | ~$258/month |
The cost profile is dominated by SageMaker processing instances running the monitoring jobs. The Bedrock narration cost is negligible — approximately $1/month for the volume of alerts a healthy production ML platform generates — because Bedrock is only invoked when a real alert fires, not on every monitoring run.
Against the cost of one silent drift incident — the retail client's demand forecasting drift resulted in an estimated ₹28–34 lakh in suboptimal inventory positioning over the 11 weeks it went undetected — the monitoring platform's infrastructure cost is recovered in the first incident it prevents.
Common Pitfalls (Real Lessons)
| Pitfall | What Happened | How We Fixed It |
|---|---|---|
| Baseline computed on a small training sample | Model Monitor flagged 60% of features as drifted on day one — all false positives | Recomputed baseline on full training dataset; minimum 10,000 records required |
| Alert thresholds set too tight on high-variance features | PagerDuty fatigue — team started ignoring alerts within two weeks | Analyzed 30-day metric history before setting thresholds; applied percentile-based bands not fixed values |
| Data capture at 100% sampling | S3 storage costs ballooned to $340/month in week one | Set sampling to 20% — statistically sufficient for drift detection at our volumes |
| Step Functions retraining triggered on a data pipeline outage | Model retrained on 3 days of incomplete data, performance regressed | Added data completeness gate before retraining trigger: >95% feature completeness required |
| QuickSight dashboard showed raw violation counts | Business stakeholders interpreted every violation as a crisis | Changed primary metric to composite health score (0–100) with clear RAG thresholds and plain-language status descriptions |
Each of these mistakes was instructive. The hardest lesson was the alert threshold problem — a monitoring system that people stop reading is worse than no monitoring at all, because it creates a false sense of coverage while providing none.
Business Outcomes
| Metric | Before | After | Business Impact |
|---|---|---|---|
| Mean time to detect model degradation | ~47 days | < 72 hours | Drift caught before business decisions are affected |
| Monitoring coverage | 1 of 4 models (ad hoc) | 4 of 4 models (automated, continuous) | Full production fleet visibility |
| Data science time on reactive investigation | ~35% of sprint capacity | ~8% of sprint capacity | Freed for model improvement work |
| Silent drift incidents (annualised) | 3 known, unknown unknowns | 0 since platform launch | Planning team trust in model outputs restored |
| Stakeholder alert actionability | Raw violation reports — ignored | Bedrock-narrated, audience-targeted alerts | Right action taken within 4 hours of alert |
| Compliance audit readiness | No documentation trail | Full incident history with actions and resolutions | Audit-ready model governance record |
The most significant shift was not technical — it was cultural. Before the monitoring platform, the data science team was in a reactive posture: something would break, someone would complain, the team would investigate. After the platform, the team is in a proactive posture: the system alerts them to an emerging issue, they investigate and resolve it before it surfaces as a business complaint. That shift from reactive to proactive is the organizational value of model observability, and it doesn't appear on an AWS cost report.
Lessons for Technology Leaders
- A model that produces predictions without health visibility is a liability, not an asset — Every ML model in production is making a claim about the world. As the world changes, that claim becomes less reliable. Without continuous monitoring, you have no way to know when to stop trusting it — and neither does the business.
- Data quality monitoring is more valuable than accuracy monitoring for models with delayed ground truth — If your model's outcomes take weeks or months to observe, waiting for accuracy metrics means waiting for the damage to be done. Monitor the inputs. Input distribution shift is an early warning signal for accuracy degradation — often days or weeks ahead of the accuracy drop itself.
- Monitoring thresholds must be calibrated on real traffic, not set by intuition — Thresholds set too tight create alert fatigue and teams that ignore monitoring. Thresholds set too loose miss real issues. Spend the time analyzing 30 days of metric history before setting any threshold. The time investment pays back in monitoring that people actually trust and act on.
- Alert communication is a product, not a side effect — An alert that a data scientist understands but a business stakeholder ignores is a monitoring failure. Invest in audience-targeted communication. The Bedrock narration layer added minimal cost and dramatically changed how quickly appropriate actions were taken on drift events.
- Automated response is the destination, not the starting point — Start with alerting. Add dashboards. Build stakeholder trust in the monitoring data. Only then introduce automated retraining triggers — once the team has validated that the monitoring signals are reliable enough to act on autonomously. Automation built on unvalidated signals creates more problems than it solves.
About the Author
Chandni Gadhvi is Program Manager – Data and AI at AeonX Digital Technology Limited, where she leads the architecture and delivery of cloud-native AI and MLOps solutions for enterprise customers. She specializes in building production-grade ML systems on AWS that are observable, governable, and continuously improving. She is an advocate for operationally mature AI — the kind that earns and keeps business trust over time — and shares technical thought leadership to help engineering teams close the gap between ML in development and ML in production.


